Natural Language Processing with PyTorch for Sentiment Analysis
Stephen Cheng
Intro
Natural Language Processing (NLP) is a critical component of modern AI, enabling machines to understand and respond to human language. PyTorch, a popular open-source machine learning library, provides robust tools for NLP tasks due to its flexibility and efficient tensor computations. Its dynamic computational graph also aids in easily modifying and building complex models.
Tensors
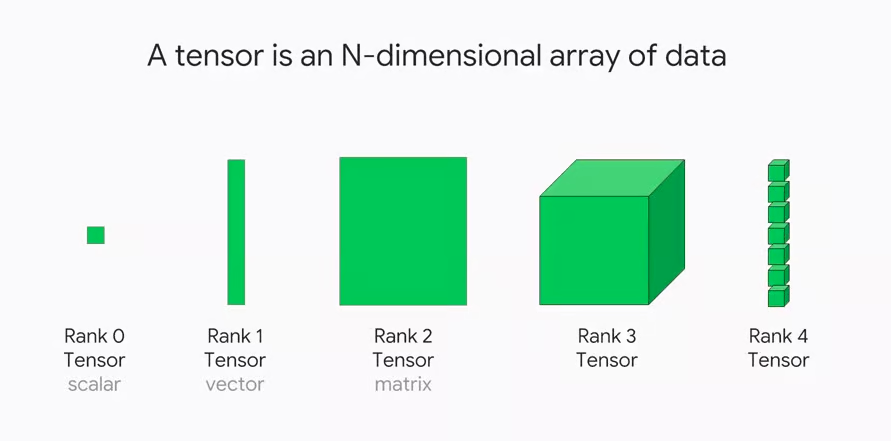
Tensors are fundamental data structures in mathematics and physics that generalize scalars, vectors, and matrices. They are multi-dimensional arrays capable of storing and manipulating large amounts of numerical data efficiently. Tensors have a defined shape, size, and data type, making them versatile for various computational operations.
In the context of PyTorch, tensors are the primary building blocks and data representation objects. Tensors in PyTorch are similar to NumPy arrays but come with additional functionalities and optimizations specifically designed for deep learning computations. PyTorch’s tensor operations leverage hardware acceleration, such as GPUs, for efficient computation of complex neural networks.
Tensors play a critical role in natural language processing (NLP) tasks due to the inherent sequential and hierarchical nature of language data. NLP involves processing and understanding textual information. Tensors enable the representation and manipulation of text data by encoding words, sentences, or documents as numerical vectors.
Word Embeddings
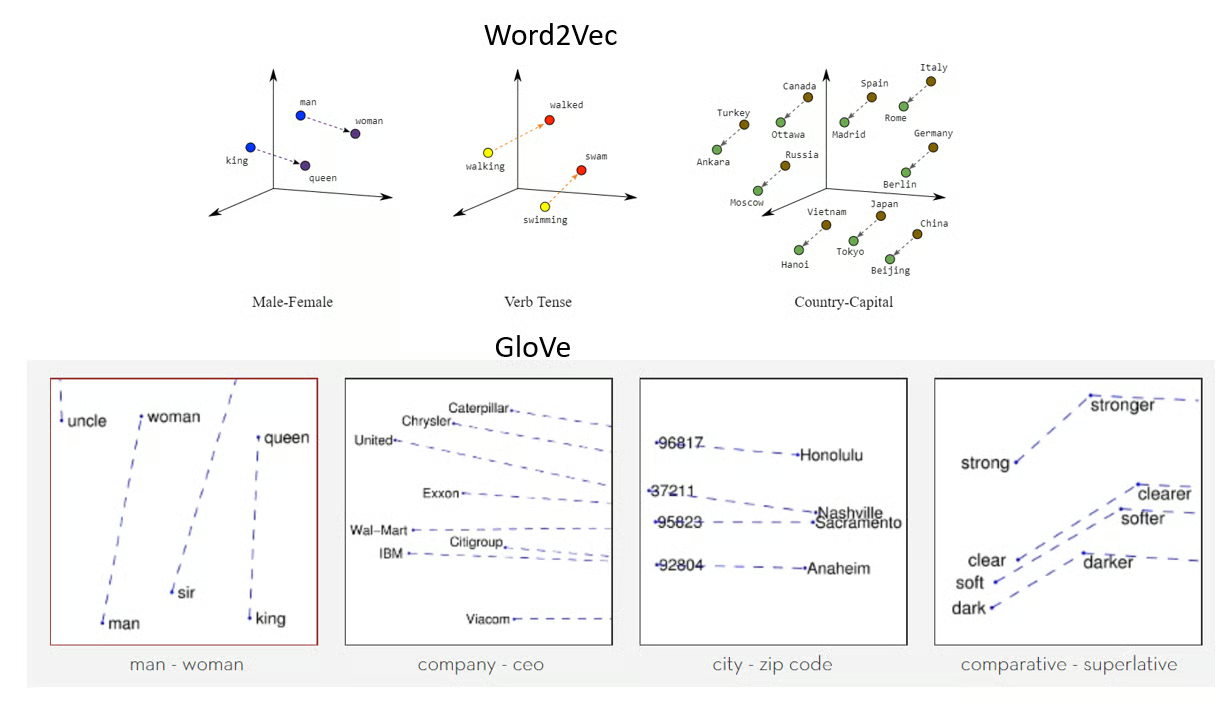
Word embeddings are dense vector representations of words in a continuous vector space. They aim to capture semantic and syntactic relationships between words, allowing for better understanding and contextualization of textual data. By representing words as numerical vectors, word embeddings capture semantic similarities and differences, enabling algorithms to work with words as meaningful numerical inputs.
Word2Vec and GloVe are two popular methods for generating word embeddings. Word2Vec is a neural network-based model that learns word representations by predicting the surrounding words given a target word (continuous bag of words - CBOW) or predicting the target word based on its context (skip-gram).
GloVe (Global Vectors for Word Representation) is a count-based method that constructs word vectors based on the co-occurrence statistics of words in a large corpus. It captures global word relationships and often leads to better performance in word analogy tasks.
Model Architecture
Sentiment Analysis is a common task in NLP where the objective is to understand the sentiment expressed in a piece of text, often classified as positive, negative, or neutral. To tackle this task, a simple recurrent neural network (RNN) or a more advanced version called long short-term memory (LSTM) can be used.
RNNs
RNN architecture processes the text sequentially, where each word is input one after another. The network maintains a hidden state that changes with each word input, capturing the information from the sequence processed so far. This hidden state acts as the memory of the network.
However, standard RNNs struggle with long sequences due to what’s known as the vanishing gradient problem, where the contribution of information decays geometrically over time, making the network forget the earlier inputs.
LSTMs
To combat this, LSTM, a variant of RNN, was developed. An LSTM maintains a longer context or ‘memory’ by having a more complex internal structure in its hidden state. It has a series of ‘gates’ (input, forget, and output gate) that control the flow of information in and out of the memory state. The input gate determines how much of the incoming information should be stored in the memory state. The forget gate decides what information should be discarded, and the output gate defines how much of the internal state is exposed to the next LSTM unit in the sequence.
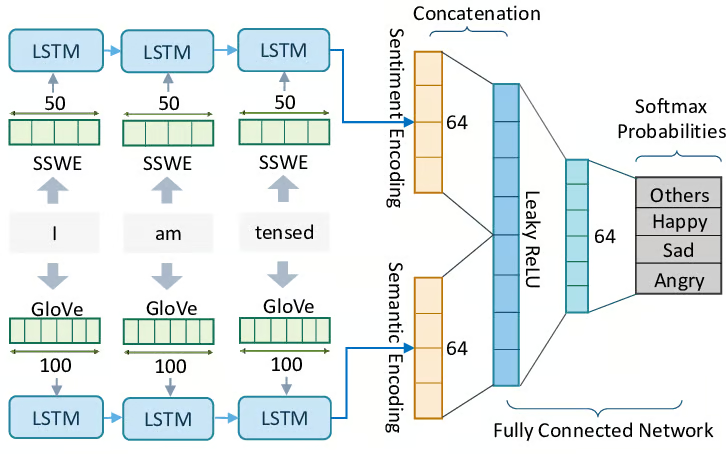
RNN or LSTM model would take a sequence of words in a sentence or document as the input. Each word is typically represented as a dense vector, or embedding, which captures the semantic meaning of the word. The network processes the sequence word by word, updating its internal state based on the current word and the previous state.
The final state of the network is then used to predict the sentiment. It is passed through a fully connected layer, followed by a softmax activation function to output a probability distribution over the sentiment classes (e.g., positive, negative, neutral). The class with the highest probability is chosen as the model’s prediction.
Training the LSTM Model with PyTorch for Sentiment Analysis
- Load the dataset
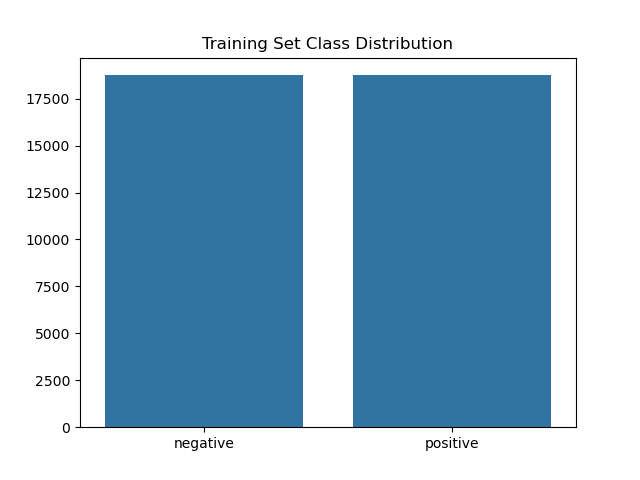
In this example, we will be using the IMDB Dataset of 50K Movie Reviews. The goal is to train a LSTM model to predict the sentiment. There are two possible values: ‘positive’ and ‘negative’. Hence this is a binary classification task.
1 | import pandas as pd |
- Exploratory data analysis
1 | import numpy as np |
- Text preprocessing
Text preprocessing and tokenization is a critical step. First, we clean up the text data by removing punctuation, extra spaces, and numbers.
We then transform sentences into individual words, remove common words (known as “stop words”), and keep track of the 1000 most frequently used words in the dataset. These words are then assigned a unique identifier, forming a dictionary for one-hot encoding.
The code essentially is converting the original text sentences into sequences of these unique identifiers, translating human language into a format that a machine learning model can understand.
1 | import numpy as np |
- Prepare the data
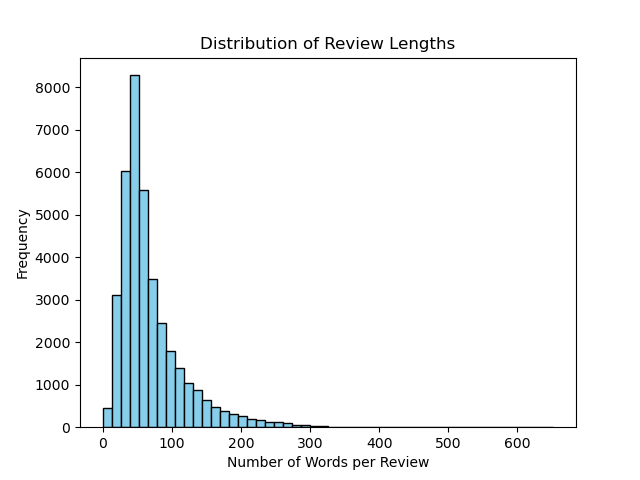
Given the variable token lengths of each review, it’s necessary to standardize them for consistency. As the majority of reviews contain less than 500 tokens, we’ll establish 500 as the fixed length for all reviews.
1 | import numpy as np |
- Define the LSTM model
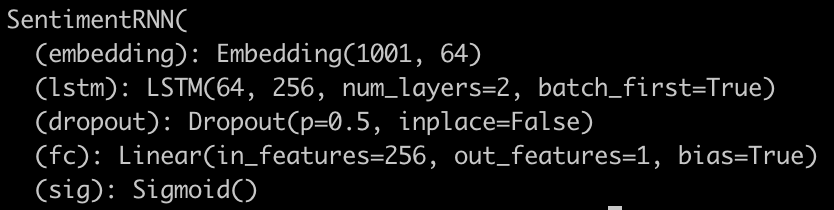
This part of the code defines a sentiment analysis model using a recurrent neural network (RNN) architecture, specifically a type of RNN called Long Short-Term Memory (LSTM) as we mentioned above. The SentimentRNN class is a PyTorch model that starts with an embedding layer, which transforms word indices into a dense representation that captures the semantic meaning of words. This is followed by an LSTM layer that processes the sequence of word embeddings.
The LSTM’s hidden state is passed through a dropout layer (for regularizing the model and preventing overfitting) and a fully connected layer, which maps the LSTM outputs to the final prediction. The prediction is then passed through a sigmoid activation function, converting raw output values into probabilities. The forward method defines the forward pass of data through this network, and the init_hidden method initializes the hidden states of the LSTM layer to zeros.
1 | import torch |
- Start training
In this part, the sentiment analysis model is trained and validated. Each epoch (iteration) involves a training phase and a validation phase. During the training phase, the model learns by adjusting its parameters to minimize the loss. In the validation phase, the model’s performance is evaluated on a separate dataset to ensure it’s learning generalized patterns and not just memorizing the training data.
The loss function used is Binary Cross-Entropy Loss (nn.BCELoss), which is commonly used for binary classification tasks. The optimization method is Adam (torch.optim.Adam), a popular choice due to its efficiency and low memory requirements. The learning rate for Adam is set to 0.001. The acc function is a helper function designed to calculate the accuracy of our model’s predictions. It rounds off the predicted probabilities to the nearest integer (0 or 1), compares these predictions to the actual labels, and then calculates the percentage of correct predictions.
The training loop starts by initializing the hidden states of the LSTM and setting the model to training mode. For each batch of data, the model’s predictions are compared to the actual labels to compute the loss, which is then backpropagated to update the model’s parameters. Gradients are clipped to a maximum value to prevent them from getting too large, it is a common issue in training RNNs and LSTMs.
In the validation loop, the model is set to evaluation mode, and its performance is assessed by using the validation data without updating any parameters. For both training and validation phases, the code tracks the loss and accuracy for each epoch. If the validation loss improves, the current model’s parameters are saved, capturing the best model found during training. After each epoch, the average loss and accuracy for that epoch are printed out, giving insight into the model’s learning progress.
1 | # loss and optimization functions |
- Model evaluation
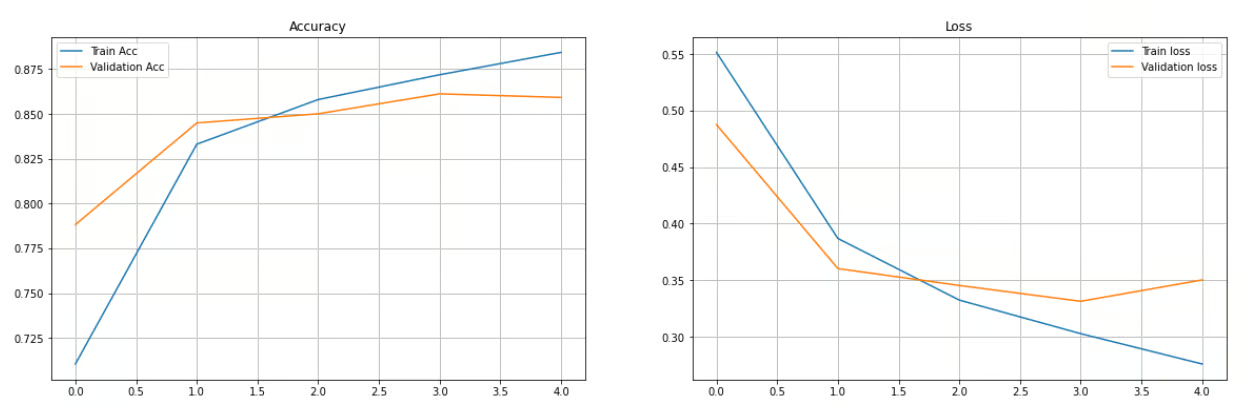
This part generates two plots to visually represent the training and validation accuracy and loss over the course of model training. The first subplot displays a line graph of the training and validation accuracy after each epoch. It is useful for observing how well the model is learning and generalizing over time. The second subplot displays a line graph of the training and validation loss. This helps us see whether our model is overfitting, underfitting, or fitting just right.
1 | fig = plt.figure(figsize = (20, 6)) |
- Inference / Prediction
In this part, we create a function predict_text for predicting the sentiment of a given text, and a demonstration of its use. The predict_text function takes as input a string of text, transforms it into a sequence of word indices (according to a pre-defined vocabulary), and prepares it for input into the model by padding and reshaping. The function then initializes the hidden states of the LSTM, feeds the input into the model, and returns the model’s output probability of the raw text.
1 | def predict_text(text): |
Improving the Model
Improving an NLP model often involves multiple strategies tailored to the specific requirements and constraints of the task at hand. Hyperparameter tuning is a common approach that involves adjusting parameters such as learning rate, batch size, or the number of layers in a neural network. These hyperparameters can significantly influence the model’s performance and are typically optimized through techniques like grid search or random search.
Transfer learning, particularly with models like BERT or GPT, has shown significant potential in improving NLP tasks. These models are pre-trained on large corpora of text and then fine-tuned on a specific task, allowing them to leverage the general language understanding they’ve gained during pre-training. This approach has consistently led to state-of-the-art results in a wide range of NLP tasks, including sentiment analysis.
Conclusion
PyTorch offers a powerful and flexible platform for building NLP models. In this post, we have walked through the process of developing a sentiment analysis model using an LSTM architecture, highlighting key steps such as preprocessing text data, building the model, training and validating it, and finally making predictions on unseen data. This is just the tip of the iceberg for what is possible with NLP and PyTorch. NLP has vast applications, from chatbots and recommendation systems to sentiment analysis tools and beyond. Mastering NLP with PyTorch is challenging yet rewarding, as it opens up a new dimension of understanding and interacting with the world around us.
Deep Learning, LSTM, NLP, PyTorch, Sentiment Analysis — Feb 9, 2026
Search
Made with ❤️ and ☀️ on Earth.